Updated September 2026 — Lead scoring helps a small team decide which conversations deserve attention first. The useful version is not a magic number and it is not a promise that a score predicts revenue. It is a shared set of definitions that turns relevant customer information and observable behavior into a review order.
A good model makes the next action clearer. A representative can see why a contact is worth a prompt follow-up, why another contact needs more education, and why a third should not be routed to sales yet. Marketing, sales, and operations can then discuss the same evidence instead of arguing over labels such as “hot” or “cold.”
This guide shows how to build a lead scoring system for a small business or revenue-operations team. It separates fit from intent, adds careful negative signals, protects customer data, defines a human handoff, and creates a review loop. The point values in the examples are illustrative only; your team must test its own definitions against real outcomes.
What lead scoring should help your team decide
Before assigning points, write down the decision the score is supposed to support. A score can help a team choose which inquiry to review first, which account needs a human handoff, which contact belongs in education, or which record needs clarification. It should not silently become a price, eligibility decision, credit decision, or automatic customer classification.
Use plain lifecycle labels that your team can observe. For example:
- New inquiry: a person or organization has made contact, but the team does not yet know whether the request fits.
- Qualified inquiry: the request matches the service area or use case and contains enough context for a responsible next step.
- Sales-ready review: a person has shown a defined combination of fit and intent that a human should assess promptly.
- Education or nurture: the request may fit, but the person needs an answer, comparison, example, or timing before a sales conversation.
- Closed or disqualified: the team has a documented reason that the request is outside the current service, timing, or audience.
These labels are not interchangeable. A person can have strong intent and still be a poor fit for the current service. Another person can be an excellent fit but have shown only early research behavior. Keeping those dimensions separate is the foundation of a useful score.
Separate fit from intent before you add points
Dopasowanie describes whether the person, account, location, need, and timing match the service your business can actually support. Depending on the business, fit may include industry, company size, service area, role, use case, or an explicit answer to a qualification question. Use only information the person has supplied or the business is allowed to use for this purpose.
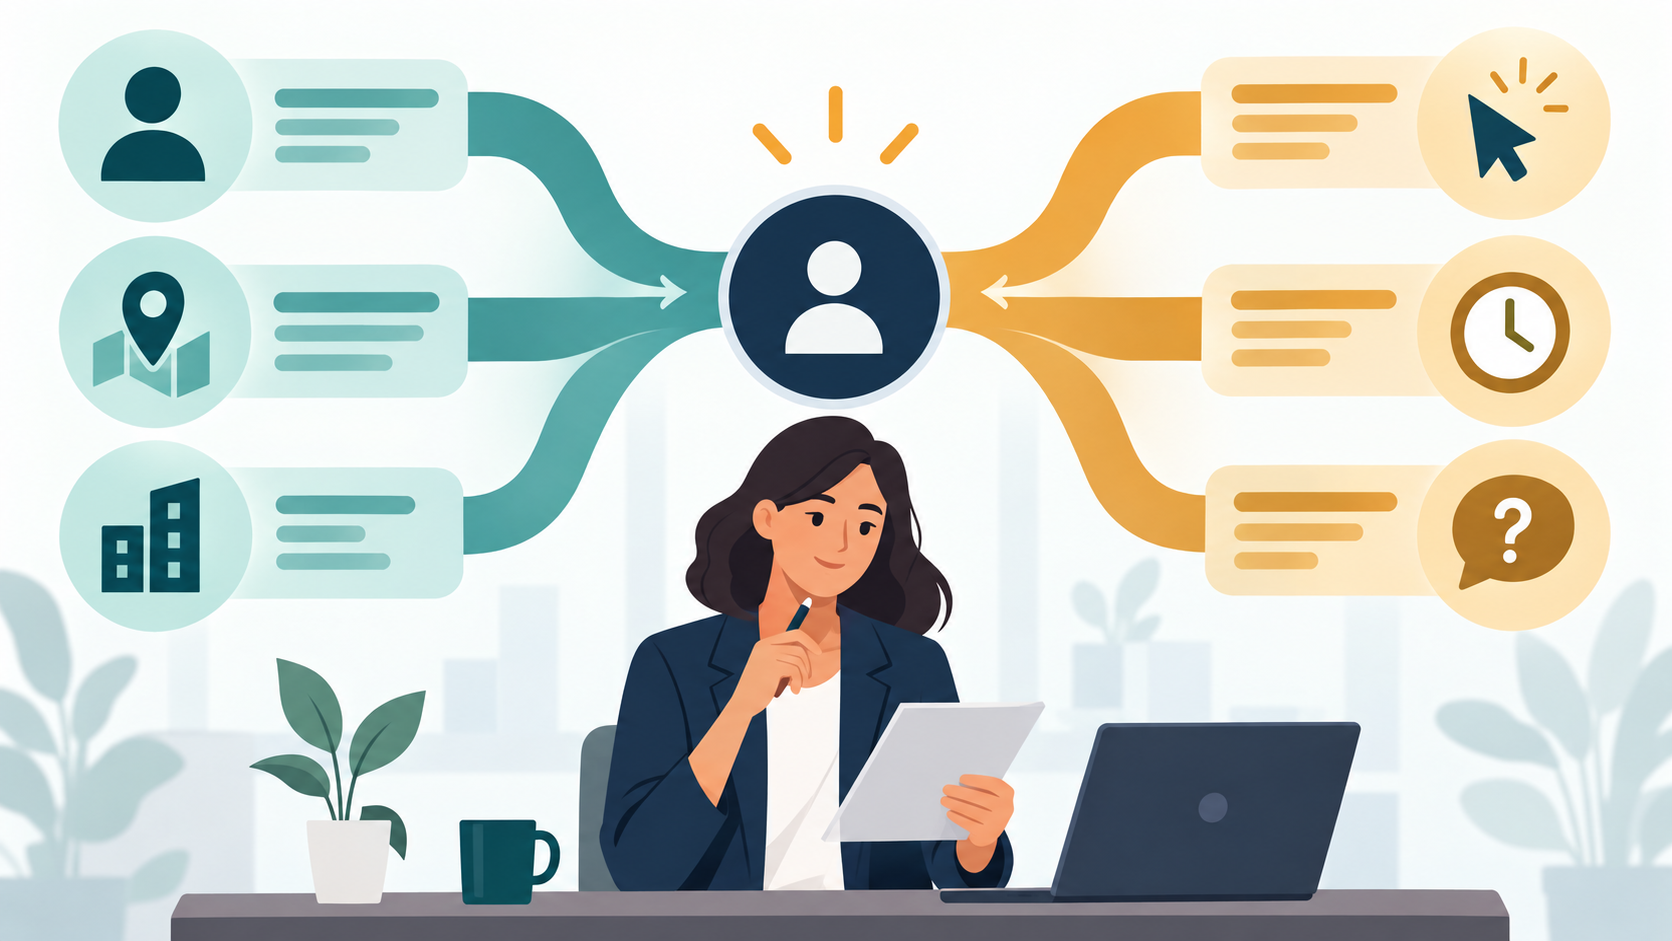
Zamiar describes what the person is doing now. A direct request for a quote, a return visit to a service page, an appointment question, or a reply to a useful guide may show more active interest than a single page view. Intent is about behavior and stated need, not about guessing a person’s identity or ability to pay.
Write the two lists separately. If a factor cannot be explained as either fit or intent, it may be an unhelpful proxy. For example, a job title might be a reasonable fit signal in one business and irrelevant in another. A device type or a broad location may be useful for routing, but it should not be treated as a measure of personal value.
When the business serves consumers rather than accounts, keep the model simple. Service type, service area, preferred timing, preparation needs, and a clear question may be enough. The goal is a better next step, not a surveillance profile.
Define the qualification rule your score must support
Choose the smallest set of conditions that a human would need before taking the next action. A home-services team may need the service type, location, timing, and a safe way to follow up. A software team may need the use case, team context, decision timing, and whether the request is for evaluation or support. A salon may need the service, preferred timing, location, and preparation question.
Write the rule in a sentence: “A sales-ready review requires a supported use case, a serviceable location, a current need, and a clear next step.” Then list what would make the rule fail. A request outside the service area, a support issue that belongs to an existing customer queue, or a question that needs a licensed professional may need a different handoff rather than a lower score.
Keep qualification separate from urgency. Someone can need an answer quickly without being a sales opportunity. If your score combines urgency, fit, and intent into one opaque number, the person handling the record cannot tell which part needs attention.
Build a fit model that the team can explain
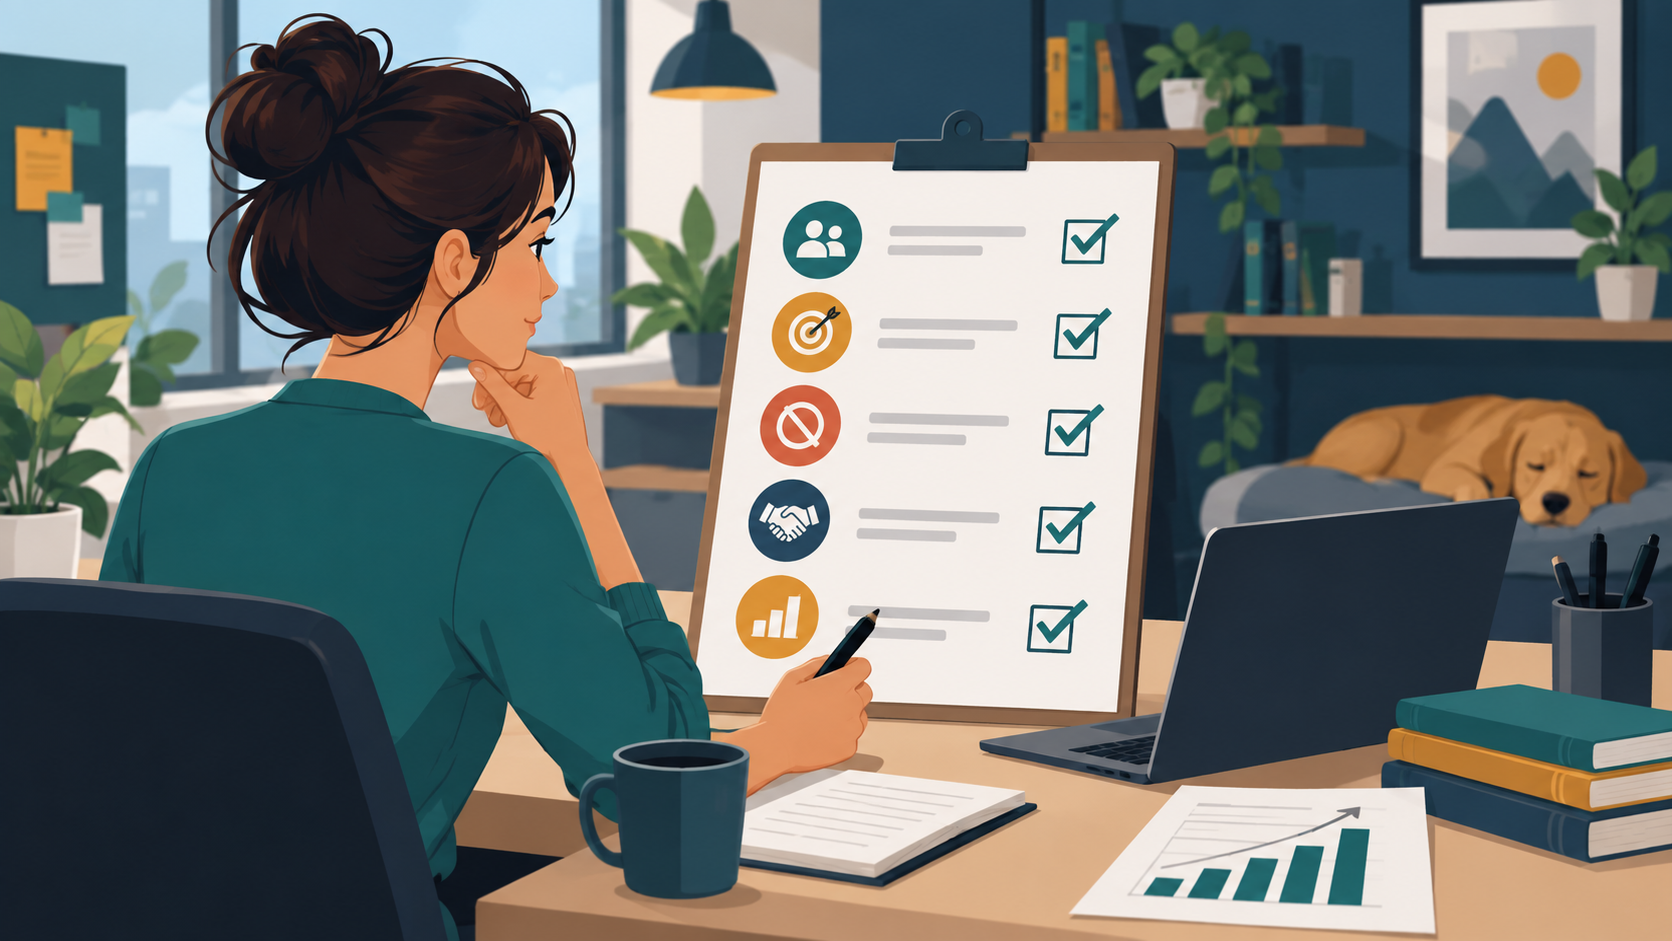
Start with two to five fit signals. Each should have an observable definition and a clear reason for inclusion. Avoid a long list that looks scientific but cannot be kept current.
| Fit signal | Example definition | Review question |
|---|---|---|
| Use case | The stated need matches a service the team supports. | Can the team describe the next useful step without inventing a capability? |
| Service area | The location or delivery scope is inside the current operating area. | Does the team have an approved way to serve this area? |
| Role or context | The person identifies a role or situation relevant to the decision. | Does this context change who should review the request? |
| Czas | The stated timeframe matches the team’s current availability. | Can the team set an honest response expectation? |
| Constraints | The request includes a requirement the service can or cannot support. | Should this be routed to a specialist or human review? |
Use a small number of levels rather than pretending that every detail deserves a precise value. For example, an in-area request can be “supported,” “needs confirmation,” or “outside current scope.” The labels should be understandable to a new team member reading the record months later.
Measure intent with behavior and stated need
Intent signals work best when they describe an action that has a known meaning in your own funnel. A person who asks a specific service question has supplied stronger context than someone who only opens a page. A repeat visit to a pricing or preparation page may be useful evidence, but it is not proof that the person is ready to buy.
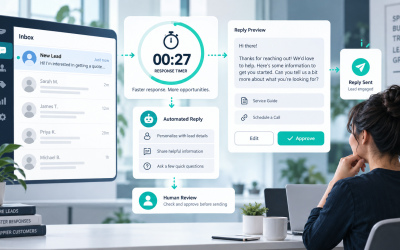
Use event definitions that can be audited. “Helpful response sent” should mean that the response addressed the question or explained the next handoff. “Booking confirmed” should mean the approved calendar or booking system confirmed it, not merely that a link was clicked. The speed-to-lead response-time workflow is a useful companion for separating receipt time, first human response, and first useful response.
Do not count every event forever. Repeated page views may indicate research, but after a period of inactivity the signal should lose weight. A single download or form start should not overwhelm a clear fit mismatch. The model should reflect how your team actually follows up, not how many events a tracking system can collect.
Use negative scoring to protect attention
Negative scoring is a way to keep a strong-looking record from being routed to the wrong queue. It should not punish a person or make a hidden judgment about their worth. The deduction should correspond to a documented routing reason.
- A request is clearly outside the service area.
- The person is asking for a support action that belongs to an existing customer process.
- The record is a job application, vendor inquiry, or partnership request handled by another team.
- The person unsubscribed from a channel or asked not to receive a particular type of update.
- The information is stale and the team cannot confirm that the need is current.
Pair each negative signal with a safe action. “Outside service area” might route to a referral list or a courteous fit response. “Do not contact” must be treated as a preference or suppression state, not as a low score. “Support request” should go to support. A numeric deduction must never override a legal, privacy, accessibility, or safety handoff.
Model time decay without hiding a customer’s history
Intent changes. A page visit from yesterday may be more useful for a current campaign than the same visit from six months ago, while a stable account relationship may remain important for a different reason. Use time windows that the team can explain, such as “recent,” “aging,” and “stale,” instead of a complicated formula that nobody reviews.
Document the event date and the rule that changes its weight. Do not delete the underlying history merely because the score decayed. A later human can still understand what happened and why the current action differs from the past action. If a person returns, the new event should be evaluated under the current model rather than silently restoring an old label.
Create a handoff threshold that means something
A threshold is a workflow decision, not a universal benchmark. Choose it after the team has written examples of records that should receive a prompt human review and records that should not. The threshold should answer: “What combination of evidence is enough for the next responsible person to look now?”
Use a bounded pilot. Start with a small sample, record why each record crossed the threshold, and compare the label with the eventual outcome. If the score sends too many low-context inquiries to sales, the fit definition may be weak. If it misses clear requests, the intent events or threshold may be too strict. Change one part at a time so the team can explain the result.
For a Messenger Bot workflow, a conversation can collect a non-sensitive routing detail and tell the person when a human will review it. Do not promise that a score confirms a booking, qualifies a person automatically, or replaces staff judgment. Keep the customer-facing response grounded in the request and give a human path for unusual, sensitive, or high-impact questions.
An illustrative scoring table for a small team
The table below is a teaching example, not an industry standard. Replace every factor, point value, and threshold after reviewing your own outcomes. A score is useful only when the team can inspect the evidence behind it.
| Evidence | Illustrative points | Dlaczego to ważne | Suggested next step |
|---|---|---|---|
| Supported use case stated | +10 | Shows the request may fit the service. | Keep in the qualification queue. |
| Serviceable location confirmed | +5 | Removes a delivery uncertainty. | Continue with the approved question. |
| Specific timing or availability question | +8 | Shows a concrete planning need. | Offer the next human-reviewed step. |
| Returns to a relevant preparation or pricing page | +4 | May indicate active research. | Check that the page answers the question. |
| Clearly outside current service scope | -15 | Prevents an unsupported handoff. | Use a respectful fit response or referral. |
| Request is support, privacy, payment, or safety related | Do not score | These require the responsible human path. | Escalate; do not let a number decide. |
In this example, a team might review a record at 20 points, but that number has no meaning until the team tests it. If the evidence is incomplete, “needs information” is a better disposition than adding points to force a handoff.
Connect scoring to a human operating rhythm
A scoring model fails when it exists only in a dashboard. Assign an owner for daily review, an owner for model changes, and an owner for data-quality questions. Decide what happens when a record has no score, conflicting signals, duplicate records, or an urgent request that does not fit the model.
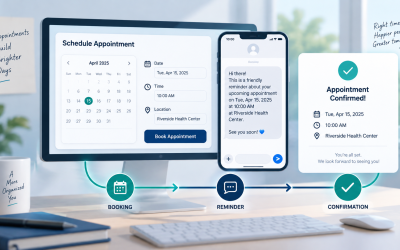
Write a short service-level expectation for each queue without promising a response time the team cannot deliver. A high-priority review may mean “check during staffed hours,” while an education queue may receive a scheduled follow-up. The appointment reminder templates guide shows why clear timing, next action, and reschedule language matter once a confirmed appointment exists; do not treat a reminder as proof that a lead was qualified.
Review the handoff record. It should show the reason for the score, the events and dates used, the next owner, and any customer preference that limits contact. Avoid copying sensitive content into notes when a short safe category is enough.
Measure the model without inventing success
Track process measures and outcome measures separately. Process measures show whether the model is being used: percentage of records with a reason, time from threshold to human review, and number of records returned for missing context. Outcome measures show what happened later: qualified-review rate, booking or opportunity rate where applicable, attendance or completion, and the reason a record was closed.
Use a consistent observation window. A model changed this week cannot be compared with a full quarter without labeling the difference. Keep seasonality, staffing changes, promotions, and demand shifts in the notes. A decline in qualified inquiries may be a demand change rather than a scoring failure.
Review false positives and false negatives with examples. A false positive is a record routed for prompt review that did not fit after a human checked it. A false negative is a record that looked low priority but later proved to need quick attention. Do not hide either category by changing the definition after the fact.
For measurement events, use a clear analytics vocabulary and consistent timestamps. Google’s GA4 event guidance can help teams distinguish an event name from its parameters. It does not define your qualification rules or guarantee that an event represents revenue.
Protect privacy and keep the data useful
Collect the minimum information needed for the next decision. A lead score does not justify storing passwords, payment details, government identifiers, health information, or private account data in a marketing note. If a request involves those topics, route it to the approved human or secure process instead of adding detail to the score.
Document who can see the evidence, how long it is retained, and how a person can update a preference. The FTC privacy and security guidance i NIST Privacy Framework are useful noncompeting references for thinking about safeguards and data minimization. Keep the public article practical and avoid implying that a generic framework is legal advice.
Use a fit check rather than hostile language when a request is outside the current offer. A respectful explanation and a useful alternative protect the relationship better than telling a reader that they do not belong.
A 30-day lead scoring implementation checklist
Use one evidence location and one decision owner for each step. Do not change the model and the response process at the same time unless you can explain the result.
| Week | Akcja | Evidence to keep | Decision |
|---|---|---|---|
| 1 | Write the lifecycle labels, supported use case, service area, and human handoff rules. | One-page definitions and examples. | Can a new team member apply the labels? |
| 2 | Choose two to five fit signals, two to five intent signals, and a short negative-signal list. | Scoring table with definitions and owners. | Is every signal observable and explainable? |
| 3 | Run a bounded pilot and record why each record crossed or missed the review threshold. | Dated sample, reviewer notes, customer preferences. | Which signal created the most ambiguity? |
| 4 | Review false positives, false negatives, handoff time, and outcome categories. | Change log and comparable window. | Change one rule, retain the old evidence, and set the next review date. |
The checklist is intentionally small. A team should be able to explain the score before adding predictive models, extra data sources, or automated routing.
Common lead scoring mistakes
- Confusing activity with fit: repeated clicks do not make an unsupported request serviceable.
- Using a universal threshold: a number copied from another business has no local evidence.
- Ignoring negative signals: a high activity count can mask a clear routing mismatch.
- Scoring sensitive requests: privacy, payment, security, legal, and safety questions need responsible human paths.
- Changing the model without a change log: the team loses the ability to compare periods.
- Calling a message a conversion: a sent response is not a confirmed booking or sale.
- Building a dashboard before definitions: more charts cannot repair unclear labels.
How is lead scoring different from lead qualification?
Qualification is the human or rule-based decision about whether a request fits the current service and next step. Scoring is a way to organize evidence and review order. A score can support qualification, but it should not replace the human definition of fit or override a privacy, safety, or support handoff.
What is the difference between fit and intent?
Fit describes whether the request matches the service, audience, location, context, and timing you can support. Intent describes the person’s current behavior or stated need. Strong intent with poor fit needs a respectful fit response; strong fit with early intent may need useful education before a sales review.
How do we choose a lead scoring threshold?
Start with examples your team agrees should receive prompt human review, then test a small sample. Record false positives, false negatives, missing context, and the eventual disposition. Adjust one signal or threshold at a time and keep the old evidence so the change can be evaluated honestly.
Why use negative scoring?
Negative scoring helps prevent activity from hiding a clear routing mismatch, such as an unsupported service area or a request owned by another team. It should lead to a documented next step, not a hidden judgment about the person. Suppression or privacy preferences must be honored as their own state.
How often should a team review its model?
Set a review date that matches your volume and sales cycle. A small team might review a bounded sample monthly, while a faster-moving operation may review it more often. Review after a major service, staffing, channel, or tracking change, and label seasonal periods instead of treating them as normal baseline data.
Do small businesses need formal lead scoring?
Not always. If the team receives only a few inquiries, a shared qualification checklist may be enough. A lightweight score becomes useful when several people review inquiries, response order is inconsistent, or the business needs to explain why a request was routed. Start with definitions and a short table before adding software or automation.
What should a team do next?
Write the fit definition, list the few intent signals you can actually observe, add safe negative routes, and name the human handoff owner. Run a small dated pilot, compare the evidence with the outcome, and change one rule at a time. Keep the system understandable to the person who must help the customer next.
Sources and operating notes
For measurement and privacy context, review Google Analytics event guidance, to FTC privacy and security guidance, to NIST Privacy Framework, oraz U.S. Small Business Administration marketing and sales guide. These sources provide general operating context; they do not guarantee rankings, conversions, or revenue. Keep the scoring rules and customer-facing details under your own review process.
 Polski
 English
 Tagalog
 简体中文
 العربية
 हिन्दी
 Português do Brasil
 Español de México
 Français
 বাংলা
 香港中文
 繁體中文
 Nederlands
 Deutsch
 Bahasa Indonesia
 日本語
 한국어
 Русский
 Español
 Tiếng Việt